Persistence of Reason
Abstract
I study reasoning, how it works, where it breaks, and what it takes to make it hold up, in machines and in people. My research pairs language models with formal methods, so that what a model produces can be checked rather than trusted.
1Research
all papers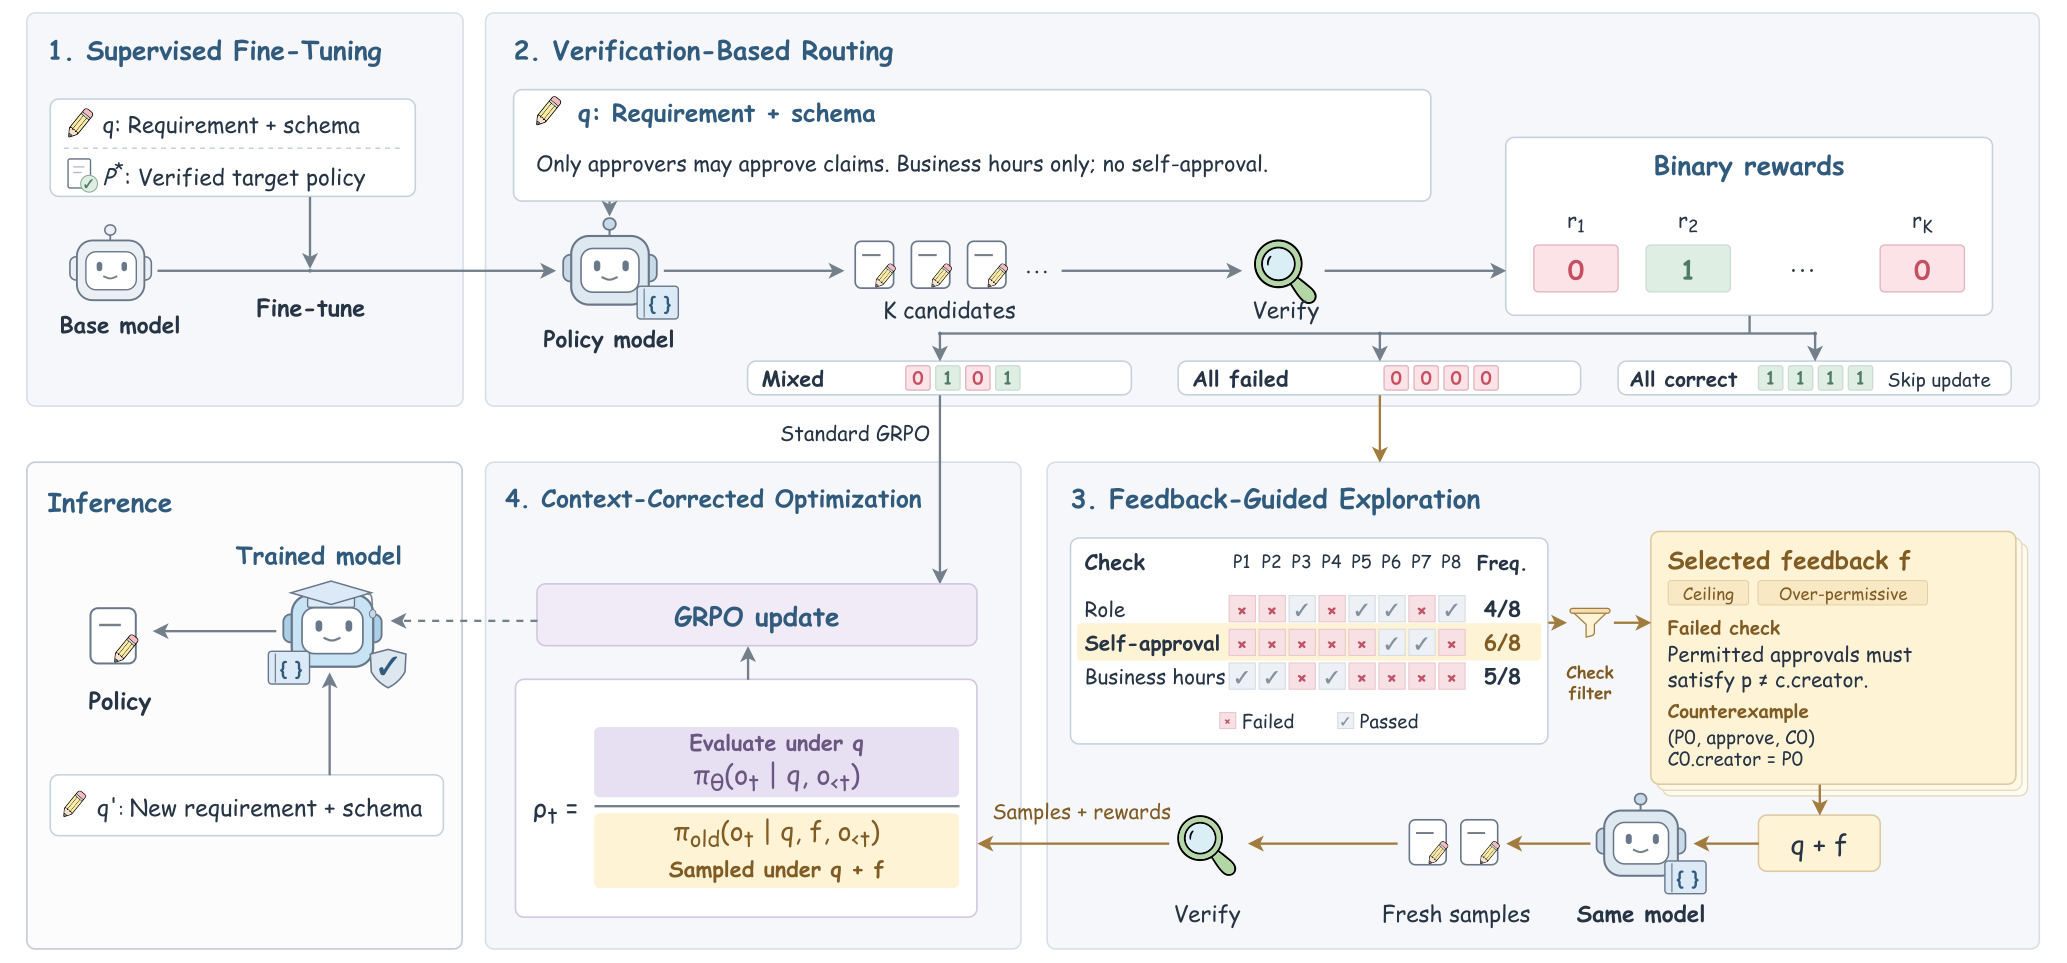 arXiv preprint, 2026
RAISE: Reinforcing Access Control Policy Synthesis in LLMs via Symbolic Evaluation
Reinforcement learning from a formal verifier trains a 9B model to beat zero-shot frontier models at writing correct Cedar policies.
 arXiv preprint, 2026
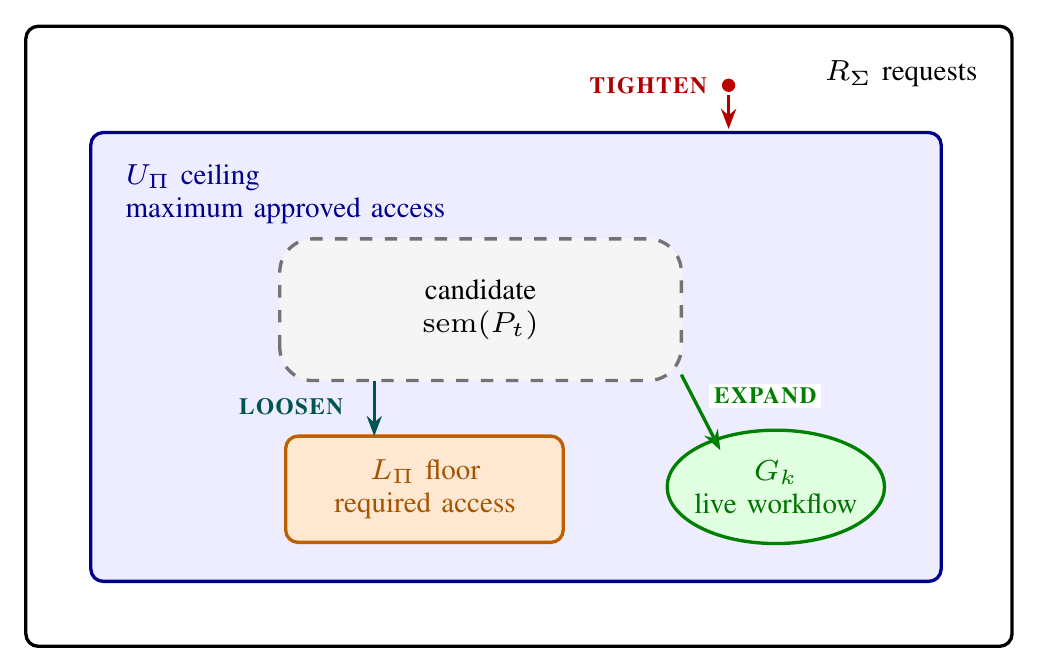
AutoCedar: An Agentic Framework for Verifier-Guided Access Control Policy Synthesis
Fix the intended meaning first, then let a verifier steer the model to a provably correct policy. Converges on all 221 CedarBench tasks.
 ISSRE 2026
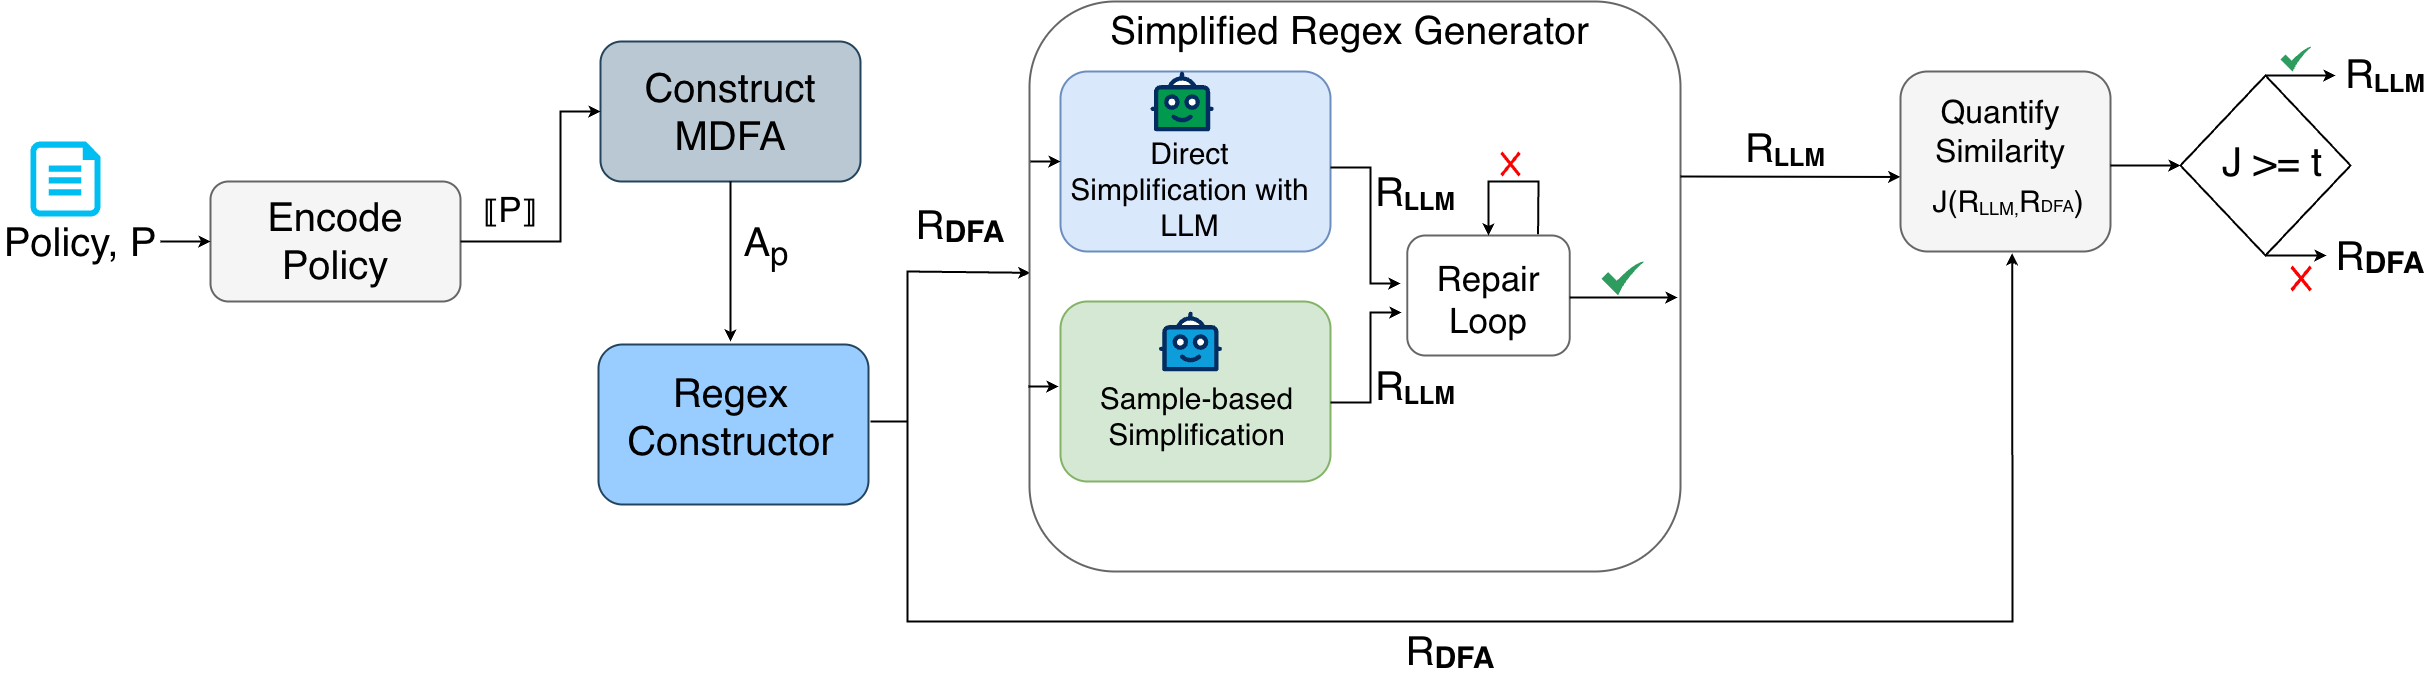
Neurosymbolic Characterization for Reliable Access Control Policy Analysis
Automata and model counting keep LLM policy summaries faithful. Raised change-review accuracy from 39 to 93 percent in a user study.
 NLBSE @ ICSE 2025
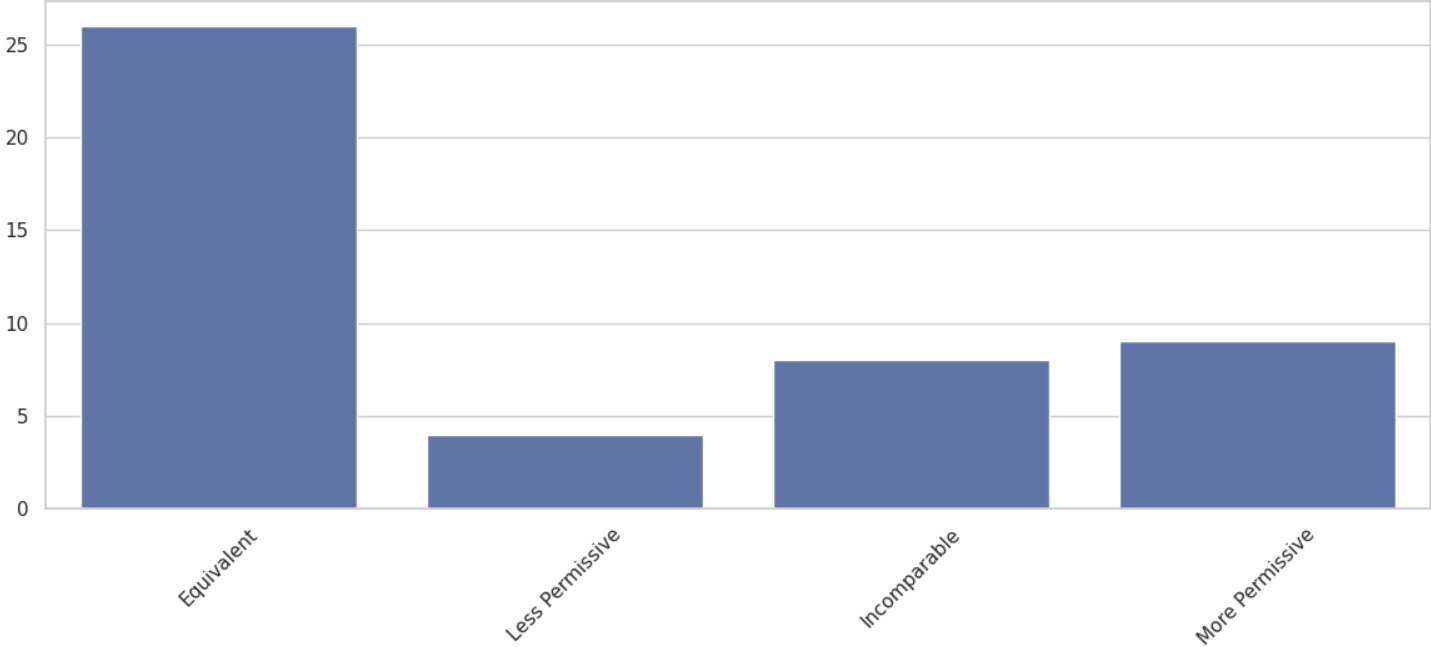
Synthesizing Access Control Policies Using Large Language Models
Zero-shot LLMs write valid cloud policies, and only precise, structured specifications make them correct.
2Correspondence
- avatsa@stevens.edu
- scholar
- Google Scholar profile
- github
- github.com/adarsh-vatsa
- feed
- RSS