Synthesizing Access Control Policies Using Large Language Models
#Question
Can a language model write a correct cloud access-control policy from a specification, with no examples? Every generated policy is checked against ground truth by SMT-based model counting, which measures exactly which requests it allows.
#Specifications
Three kinds of specification are compared on GPT-4. A concrete list of requests to allow or deny, a loose natural-language description, and a fine-grained description written in a small structured syntax.
#Results
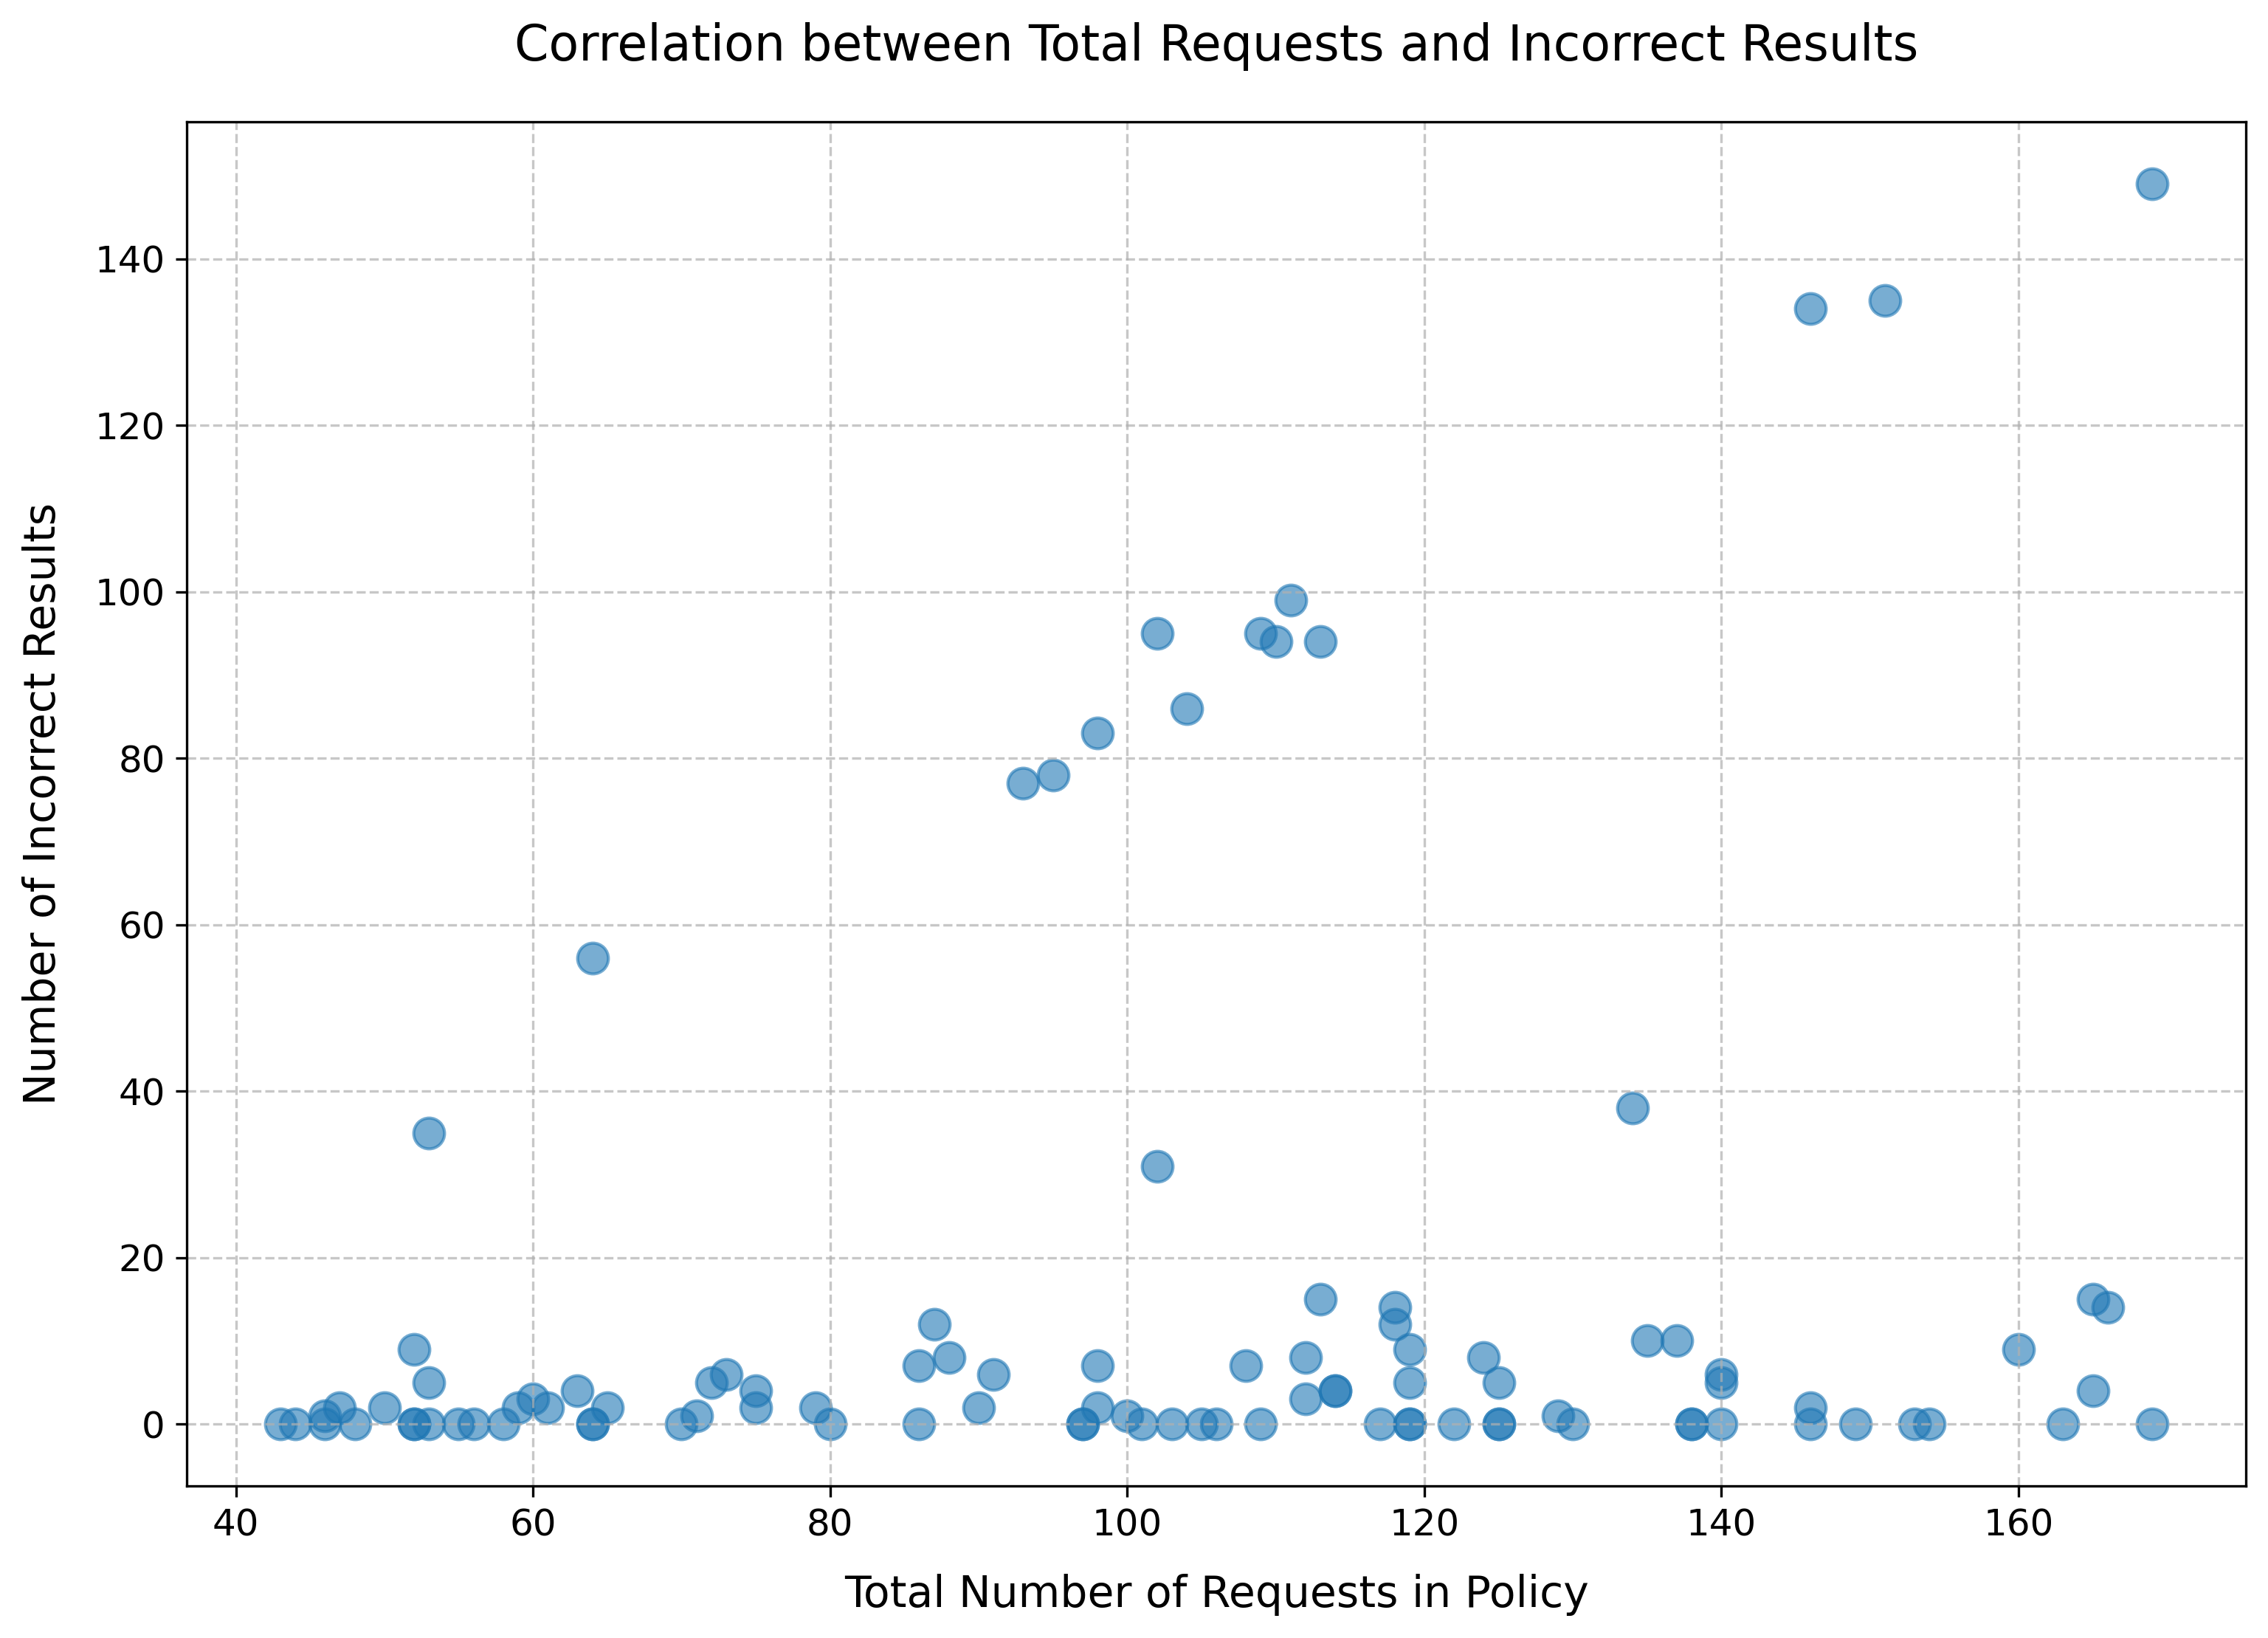
From concrete request lists, all 100 generated policies are syntactically valid100 of 100 valid and classify most requests correctly, with errors growing as lists get longer and more varied.
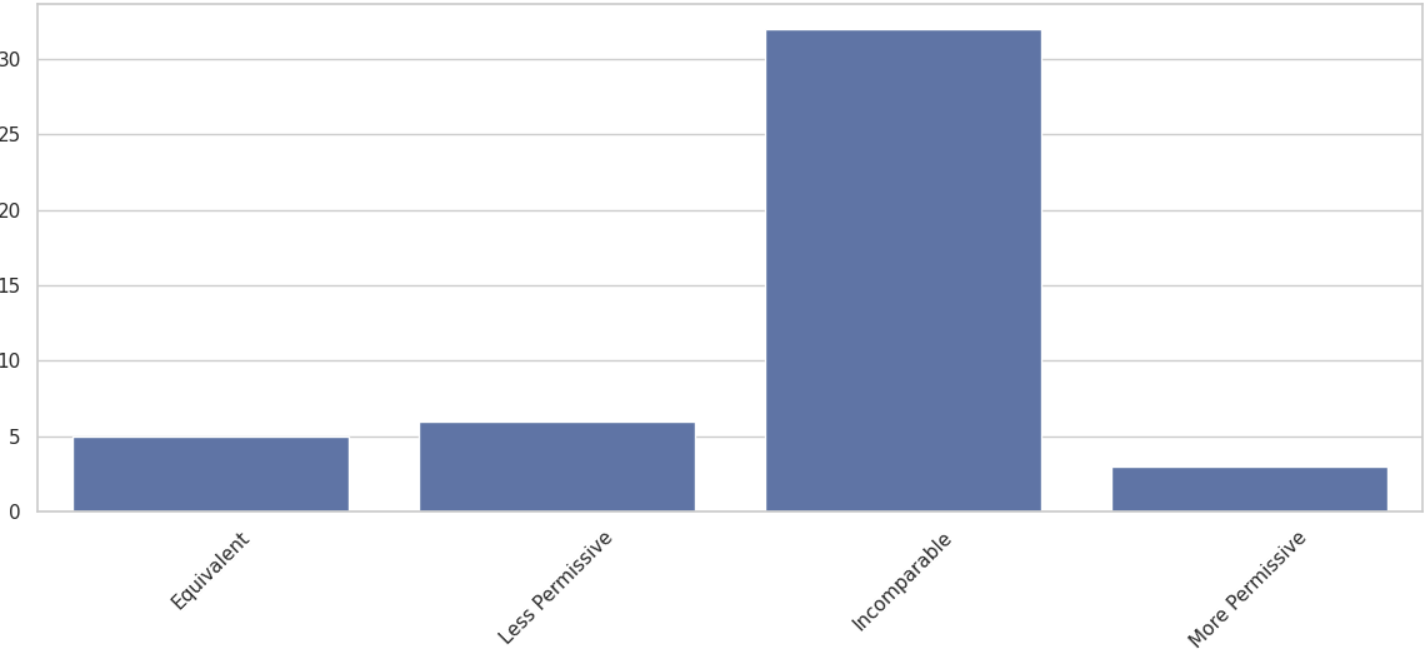
From loose natural language, most policies end up incomparable to the ground truth, usually broader than intended.
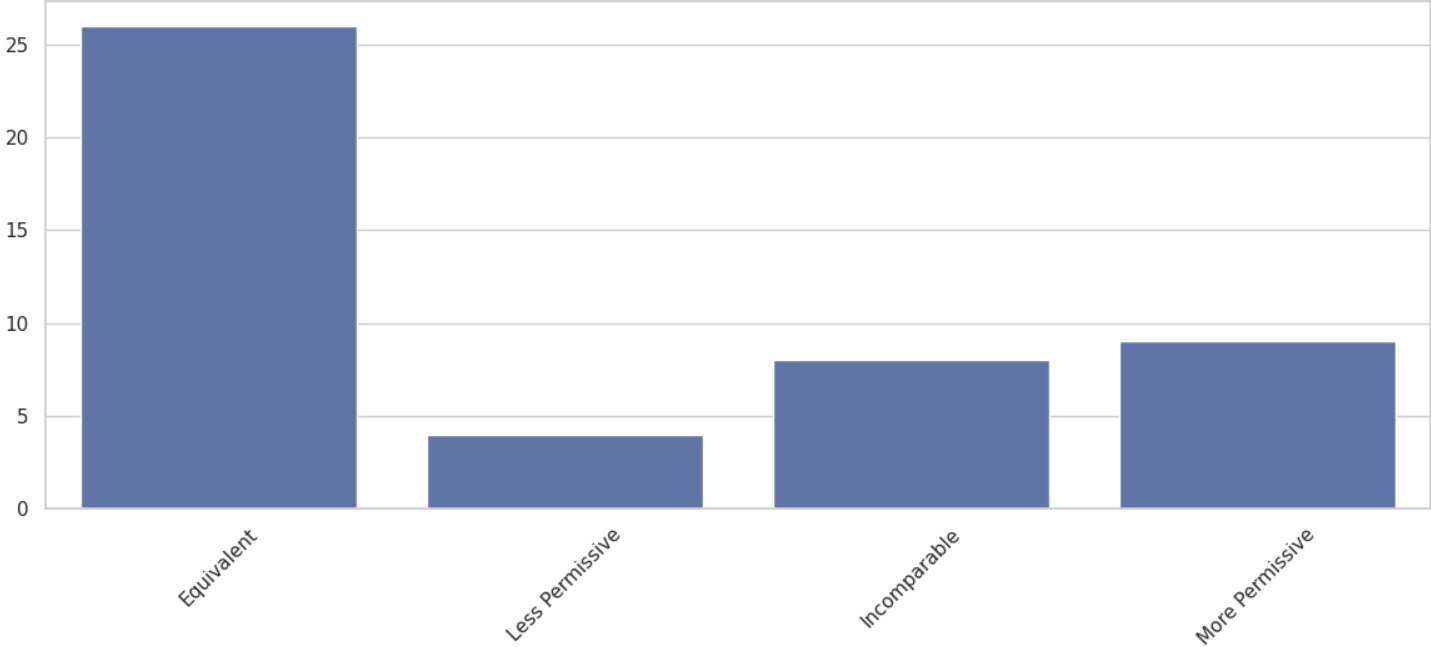
With the structured syntax, the model produces a precise policy in the majority of cases. Precise, structured specifications are what make zero-shot policy synthesis reliable.structure in the spec, precision in the policy